How We Built a Better Clinical Trial Search
Every clinical trial published to ClinicalTrials.gov is a treasure trove of structured and unstructured data —
inclusion criteria, protocol amendments, secondary endpoints, and full study documents. The problem was never a lack of data. It was that the data lived in a format designed for regulatory compliance, not for discovery.
Starting with the raw feed
We began by ingesting the full ClinicalTrials.gov data feed and normalizing it into a consistent schema. That sounds simple, but the source data spans two decades of format changes, inconsistent field usage, and free-text fields that mix dosing information with eligibility language in the same paragraph.
Rather than discard the messy parts, we built a parsing layer that extracts latent metadata — age ranges expressed in prose, therapy combinations buried in exclusion criteria, and cross-references between related studies. That metadata is what powers filters standard search tools simply don't offer.
Indexing the full document corpus
Titles and summaries only tell part of the story. The real detail — the nuance that biostatisticians and clinical operations teams actually need — lives inside the full study protocols and amendments. We built a full-text indexing pipeline so every uploaded document becomes searchable alongside the structured metadata, not just the top-level fields.
This meant investing early in a search architecture that could scale to millions of pages of source documents while still returning results in milliseconds. We optimized relevance ranking specifically for clinical language, so a search for a specific inclusion nuance surfaces the studies that matter, not just the ones with matching keywords.
Designing for the way pharma teams actually work
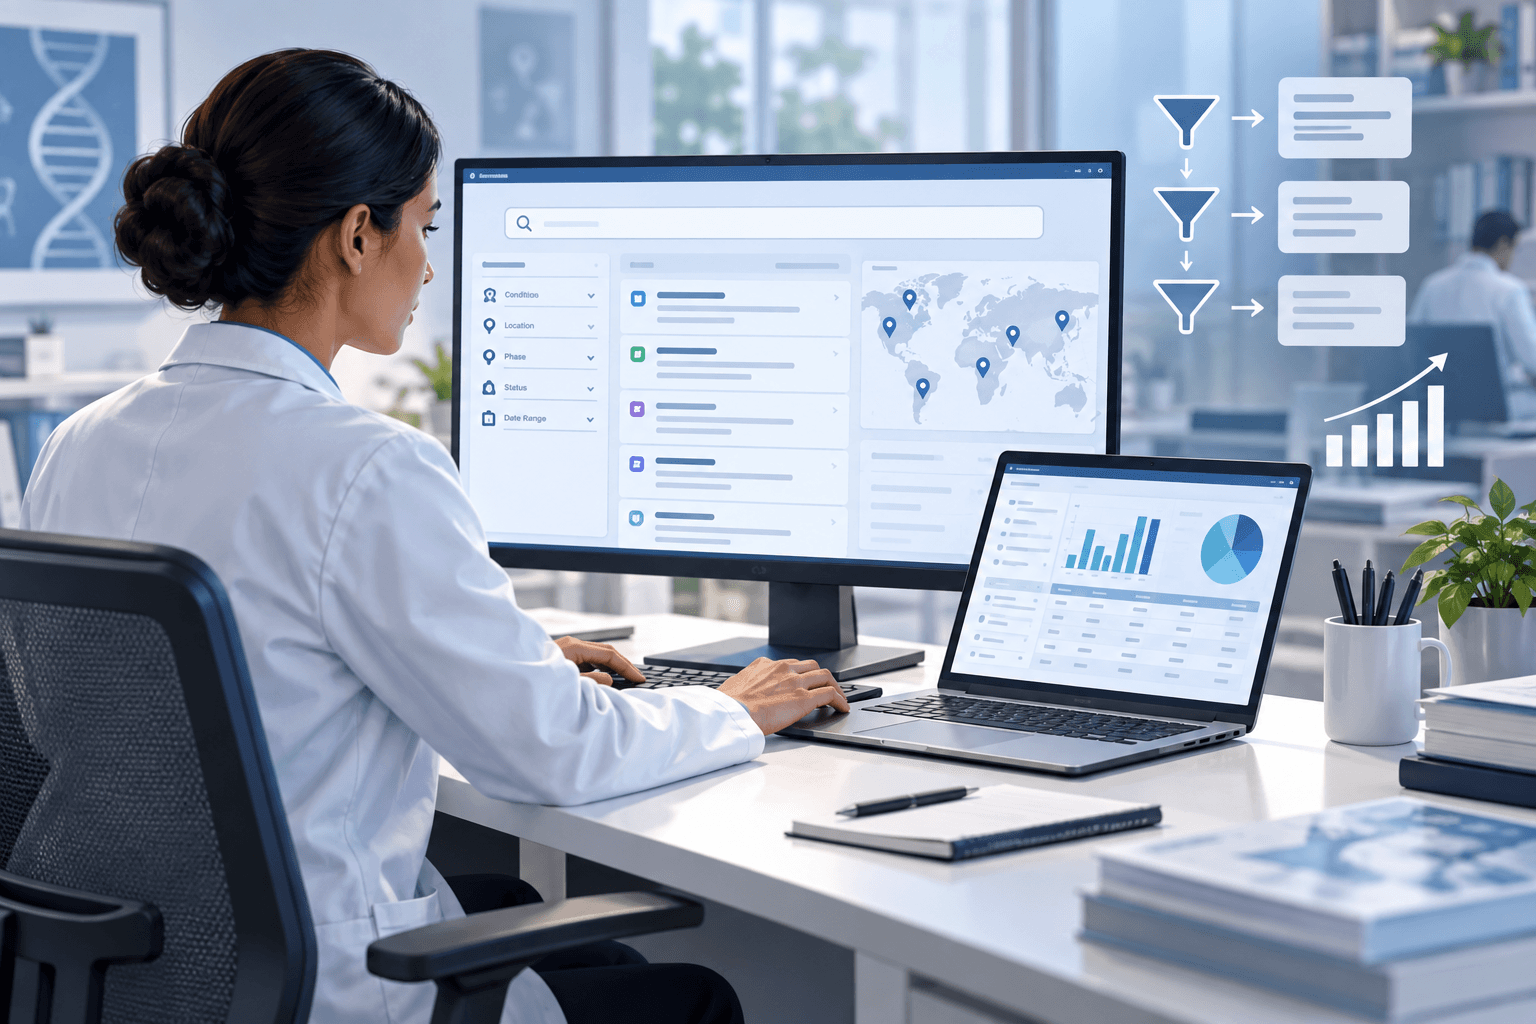
Powerful search means little if it's hard to use under deadline pressure. We spent as much time on the interface as we did on the data pipeline — advanced filters that stay out of the way until you need them, saved searches and folders for ongoing projects, and export tools that fit into existing regulatory workflows.
The result is a tool built specifically for the way biostatisticians, clinical operations teams, and regulatory professionals actually search — fast, precise, and grounded in the full depth of the data, not just the surface-level summary.